gpt-5 and gpt-5-mini rate limit updates
OpenAI have increased the rate limits for their two main GPT-5 models. These look significant:
gpt-5
Tier 1: 30K → 500K TPM (1.5M batch)
Tier 2: 450K → 1M (3M batch)
Tier 3: 800K → 2M
Tier 4: 2M → 4M
gpt-5-mini
Tier 1: 200K → 500K (5...
The trick with Claude Code is to give it large, but not too large, extremely well defined problems.
(If the problems are too large then you are now vibe coding… which (a) frequently goes wrong, and (b) is a one-way street: once vibes enter your app, you end up with tangled, write-only code which functions perfectly but can no longer be edited by humans. Great for prototyping, bad for foundations.)
— Matt Webb, What I think about when I think about Claude Code
Tags: matt-webb, claude, ai, claude-code, llms, vibe-coding, coding-agents, ai-assisted-programming, generative-ai
London Transport Museum Depot Open Days
I just found out about this (thanks, ChatGPT) and I'm heart-broken to learn that I'm in London a week too early! If you are in London next week (Thursday 18th through Sunday 21st 2025) you should definitely know about it:
The Museum D...
Claude Memory: A Different Philosophy
Shlok Khemani has been doing excellent work reverse-engineering LLM systems and documenting his discoveries.
Last week he wrote about ChatGPT memory. This week it's Claude.
Claude's memory system has two fundamental characteristics. Fir...
Qwen3-Next-80B-A3B
Qwen announced two new models via their Twitter account (nothing on their blog yet): Qwen3-Next-80B-A3B-Instruct and Qwen3-Next-80B-A3B-Thinking.
They make some big claims on performance:
Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
Qwen3-Ne...
Defeating Nondeterminism in LLM Inference
A very common question I see about LLMs concerns why they can't be made to deliver the same response to the same prompt by setting a fixed random number seed.
Like many others I had been lead to believe this was due to the non-associ...
In Python 3.14, I have implemented several changes to fix thread safety of asyncio and enable it to scale effectively on the free-threaded build of CPython. It is now implemented using lock-free data structures and per-thread state, allowing for highly efficient task management and execution across multiple threads. In the general case of multiple event loops running in parallel, there is no lock contention and performance scales linearly with the number of threads. [...]
For a deeper dive into the implementation, check out the internal docs for asyncio.
— Kumar Aditya, Scaling asyncio on Free-Threaded Python
Tags: threading, async, scaling, python, gil
Claude API: Web fetch tool
New in the Claude API: if you pass the web-fetch-2025-09-10 beta header you can add {"type": "web_fetch_20250910", "name": "web_fetch", "max_uses": 5} to your "tools" list and Claude will gain the ability to fetch content from URLs as part of resp...
I Replaced Animal Crossing's Dialogue with a Live LLM by Hacking GameCube Memory
Brilliant retro-gaming project by Josh Fonseca, who figured out how to run 2002 Game Cube Animal Crossing in the Dolphin Emulator such that dialog with the characters was instead generated by an...
There has never been a successful, widespread malware attack against iPhone. The only system-level iOS attacks we observe in the wild come from mercenary spyware, which is vastly more complex than regular cybercriminal activity and consumer malware. Mercenary spyware is historically associated with state actors and uses exploit chains that cost millions of dollars to target a very small number of specific individuals and their devices. [...] Known mercenary spyware chains used against iOS share a common denominator with those targeting Windows and Android: they exploit memory safety vulnerabilities, which are interchangeable, powerful, and exist throughout the industry.
— Apple Security Engineering and Architecture, introducing Memory Integrity Enforcement for iPhone 17
Tags: apple, privacy, security
Today on the Anthropic blog: Claude can now create and edit files:
Claude can now create and edit Excel spreadsheets, documents, PowerPoint slide decks, and PDFs directly in Claude.ai and the desktop app. [...]
File creation is now available as a preview for Max, Team, and ...
The 2025 PSF Board Election is Open!
The Python Software Foundation's annual board member election is taking place right now, with votes (from previously affirmed voting members) accepted from September 2nd, 2:00 pm UTC through Tuesday, September 16th, 2:00 pm UTC.
I've serv...
I ran Claude in a loop for three months, and it created a genz programming language called cursed
Geoffrey Huntley vibe-coded an entirely new programming language using Claude:
The programming language is called "cursed". It's cursed in its lexical structure, it's cursed in...
Anthropic status: Model output quality
Anthropic previously reported model serving bugs that affected Claude Opus 4 and 4.1 for 56.5 hours. They've now fixed additional bugs affecting "a small percentage" of Sonnet 4 requests for almost a month, plus a less long-lived Haiku ...
Apollo Global Management's "Chief Economist" Dr. Torsten Sløk released this interesting chart which appears to show a slowdown in AI adoption rates among large (>250 empoloyees) companies:
Here's the full description that accompanied the chart:
The US Census Bureau cond...
Having worked inside AWS I can tell you one big reason [that they don't document their internals] is the attitude/fear that anything we put in out public docs may end up getting relied on by customers. If customers rely on the implementation to work in a specific way, then changing that detail requires a LOT more work to prevent breaking customer's workloads. If it is even possible at that point.
— TheSoftwareGuy, comment on Hacker News
Tags: aws
Load Llama-3.2 WebGPU in your browser from a local folder
Inspired by a comment on Hacker News I decided to see if it was possible to modify the transformers.js-examples/tree/main/llama-3.2-webgpu Llama 3.2 chat demo (online here, I wrote about it last November) to add an op...
I recently spoke with the CTO of a popular AI note-taking app who told me something surprising: they spend twice as much on vector search as they do on OpenAI API calls. Think about that for a second. Running the retrieval layer costs them more than paying for the LLM itself.
— James Luan, Engineering architect of Milvus
Tags: vector-search, embeddings
Is the LLM response wrong, or have you just failed to iterate it?
More from Mike Caulfield (see also the SIFT method). He starts with a fantastic example of Google's AI mode usually correctly handling a common piece of misinformation but occasionally falling for it (the curs...
I agree with the intellectual substance of virtually every common critique of AI. And it's very clear that turning those critiques into a competition about who can frame them in the most scathing way online has done zero to slow down adoption, even if much of that is due to default bundling.
At what point are folks going to try literally any other tactic than condescending rants? Does it matter that LLM apps are at the top of virtually every app store nearly every day because individual people are choosing to download them, and the criticism hasn't been effective in slowing that?
— Anil Dash
Tags: ai-ethics, anil-dash, ai, generative-ai
The SIFT method
The SIFT method is "an evaluation strategy developed by digital literacy expert, Mike Caulfield, to help determine whether online content can be trusted for credible or reliable sources of information."
This looks extremely useful as a framework for helping p...
When I wrote about how good ChatGPT with GPT-5 is at search yesterday I nearly added a note about how comparatively disappointing Google's efforts around this are.
I'm glad I left that out, because it turns out Google's new "AI mode" is genuinely really good! It feels very ...
"Don't use chatbots as search engines" was great advice for several years... until it wasn't.
I wrote about how good OpenAI's o3 was at using its Bing-backed search tool back in April. GPT-5 feels even better.
I've started calling it my Research Goblin. I can assign a task t...
I am once again shocked at how much better image retrieval performance you can get if you embed highly opinionated summaries of an image, a summary that came out of a visual language model, than using CLIP embeddings themselves. If you tell the LLM that the summary is going to be embedded and used to do search downstream. I had one system go from 28% recall at 5 using CLIP to 75% recall at 5 using an LLM summary.
— Jason Liu
Tags: vision-llms, generative-ai, ai, embeddings, llms, jason-liu
Kimi-K2-Instruct-0905
New not-quite-MIT licensed model from Chinese Moonshot AI, a follow-up to the highly regarded Kimi-K2 model they released in July.
This one is an incremental improvement - I've seen it referred to online as "Kimi K-2.1". It scores a little higher on a b...
RDF has the same problems as the SQL schemas with information scattered. What fields mean requires documentation.
There - they have a name on a person. What name? Given? Legal? Chosen? Preferred for this use case?
You only have one ID for Apple eh? Companies are complex to ...
Anthropic to pay $1.5 billion to authors in landmark AI settlement
I wrote about the details of this case when it was found that Anthropic's training on book content was fair use, but they needed to have purchased individual copies of the books first... and they had seeded t...
After struggling for years trying to figure out why people think [Cloudflare] Durable Objects are complicated, I'm increasingly convinced that it's just that they sound complicated.
Feels like we can solve 90% of it by renaming DurableObject to StatefulWorker?
It's just a worker that has state. And because it has state, it also has to have a name, so that you can route to the specific worker that has the state you care about. There may be a sqlite database attached, there may be a container attached. Those are just part of the state.
— Kenton Varda
Tags: kenton-varda, sqlite, cloudflare
Introducing EmbeddingGemma
Brand new open weights (under the slightly janky
Gemma license) 308M parameter embedding model from Google:
Based on the Gemma 3 architecture, EmbeddingGemma is trained on 100+ languages and is small enough to run on less than 200MB of RAM with quantization.
It's available via sentence-transformers, llama.cpp, MLX, Ollama, LMStudio and more.
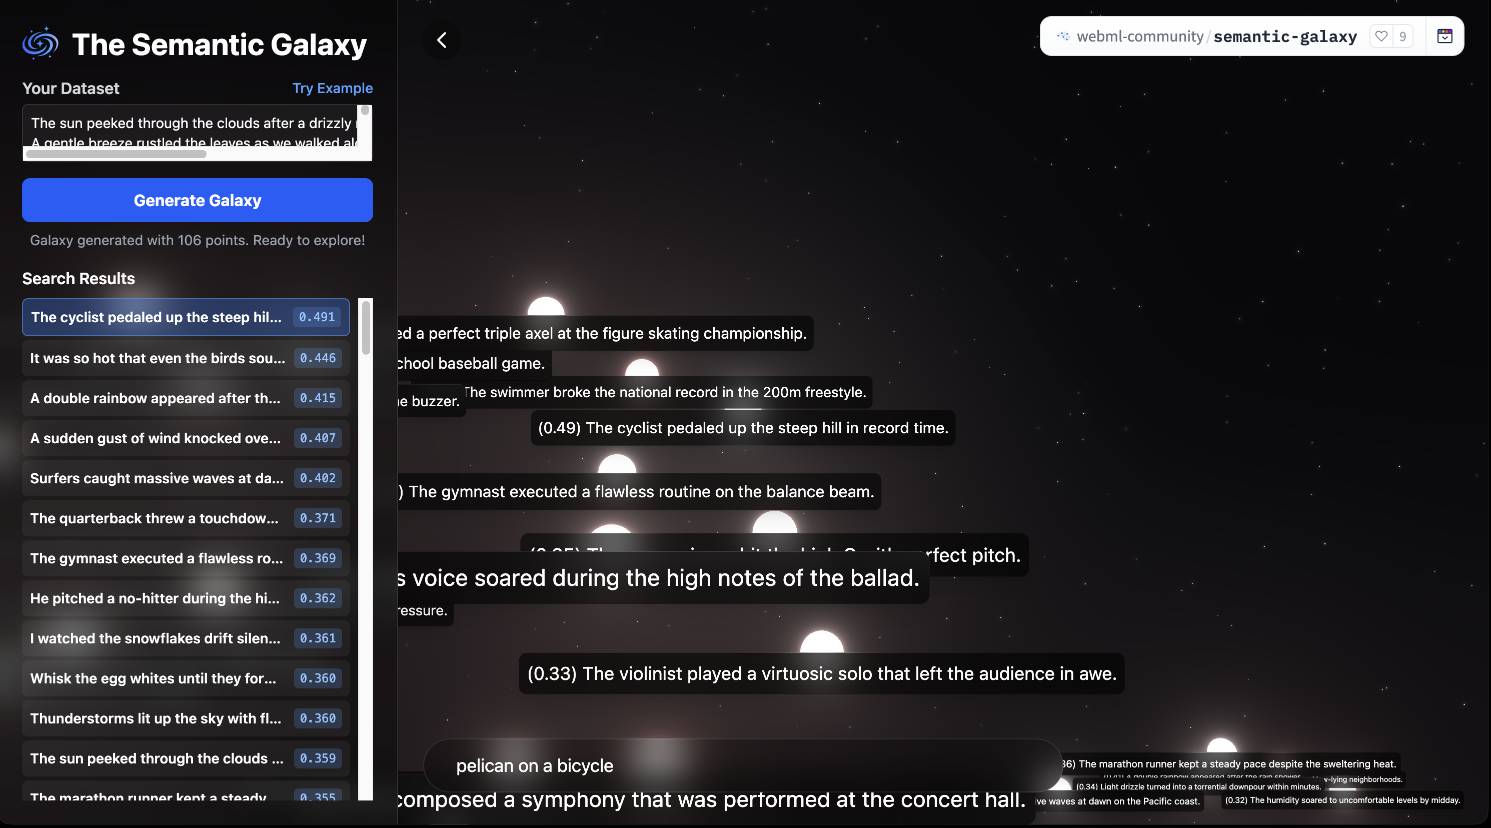
As usual for these smaller models there's a Transformers.js demo (via) that runs directly in the browser (in Chrome variants) - Semantic Galaxy loads a ~400MB model and then lets you run embeddings against hundreds of text sentences, map them in a 2D space and run similarity searches to zoom to points within that space.
Tags: google, ai, embeddings, transformers-js, gemma
Any time I share my collection of tools built using vibe coding and AI-assisted development (now at 124, here's the definitive list) someone will inevitably complain that they're mostly trivial.
A lot of them are! Here's a list of some that I think are genuinely useful and w...

 Featured